Unconfigured Ad

Collapse
X
 
  • Time
  • Show
Clear All
new posts
  • BastianOldenkott
    Junior Member
    • Oct 2015
    • 4

    #1

    RNA Seq- Problems with duplicated sequences and kmer content

    Hello everyone,

    my name is Bastian and I have a question concerning the pipeline of sequence quality improvement and control.

    My Experiment: RNA SEQ 150 bp paired-end sequencing on Illumina Hiseq4000 platform (genome size: approx. 100 Mbp) 30M reads

    My pipeline so far:
    I received 'clean data' from my company so they claim adaptors have been removed already.

    After checking the sequence quality with Fastqc, I used Trimmomatic to further improve sequence quality (HEADCROP:14 SLIDINGWINDOW:4:15 MINLEN:50).

    My problem:
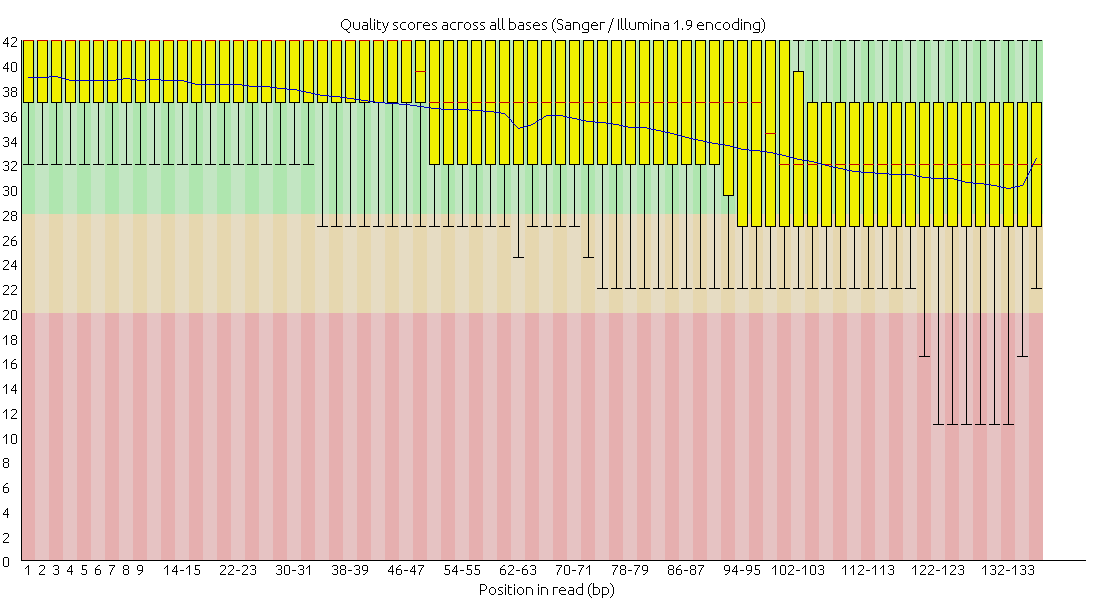
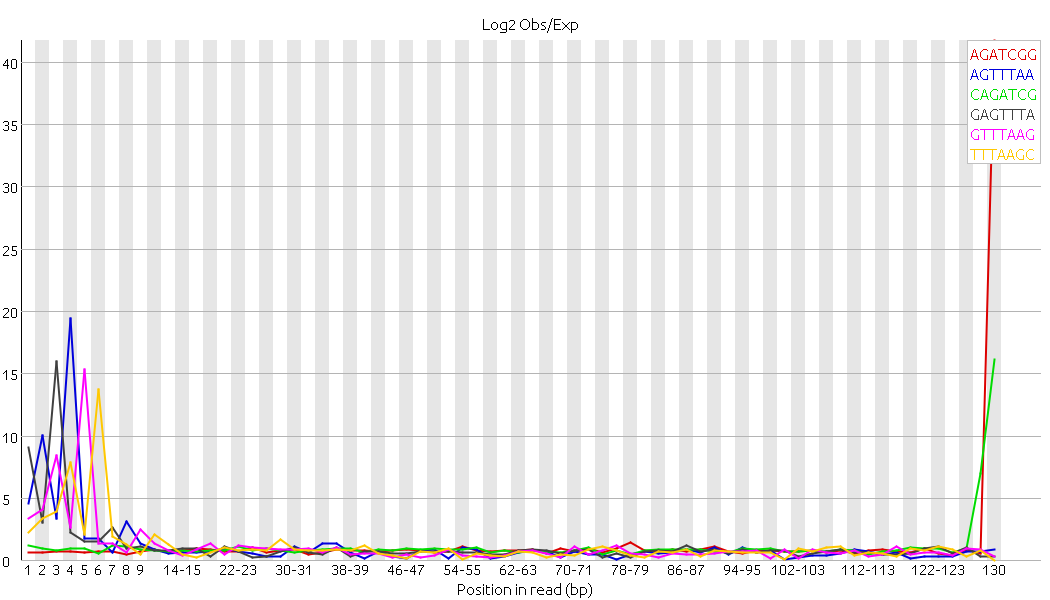
    If I check my trimmed sequences with Fastqc I still have an error symbol for Sequence duplication levels and kmer content (especially this peak at 130 bp) --> Fastqc attached

    My question(s):
    - Are those 'errors' really relevant for assembly? Especially concerning kmer content I found different opinions.
    - Which programs would you suggest to get rid of these errors? I tried abundance filtering from khmer and got a little improvement, but still the error warnings are there.

    Thank you very much (in advance) and best regards ,

    Bastian

    forward paired: http://www.directupload.net/file/d/4...dld4dd_png.htm
    http://www.directupload.net/file/d/4...5d9cxz_png.htm http://www.directupload.net/file/d/4...epa2qu_png.htm

    reverse paired: http://www.directupload.net/file/d/4...z7prvg_png.htm
    Last edited by BastianOldenkott; 10-26-2015, 07:13 AM. Reason: Images were not displayed
  • Bukowski
    Senior Member
    • Jan 2010
    • 388

    #2
    The disturbance in the first 12 bases is not at all unusual for an Illumina RNA-Seq experiment. It's been documented countless times in threads on SeqAnswers, and even has a paper: http://www.ncbi.nlm.nih.gov/pmc/articles/PMC2896536/ and this is discussed in the FastQC documentation.

    As you probably wont deduplicate the data (normally something you do after *alignment* to a reference genome for DNA-Seq) why are you concerned about it? Again there's plenty of discussion on Seqanswers about what to do with duplicates in RNA-Seq data.

    R2 files are always of a lower quality than R1 files, it's the nature of the Illumina chemistry, I didn't realise it was quite so pronounced on the 4000 though.

    FastQC is really not optimised for QC of RNA-Seq data, be warned.

    Comment

    • Brian Bushnell
      Super Moderator
      • Jan 2014
      • 2709

      #3
      I'd be interested in seeing some QC metrics of your data. The only 2x150bp HS4000 data I've seen so far looked terrible (and read 2 is FAR worse than read 1), and would need stringent trimming and filtering before being usable, but that was just one run. In order to get QC metrics, I suggest you try this:

      First, acquire the raw data so that you can preprocess it optimally. Then adapter-trim it as indicated here.

      From your histograms, it looks like you did not get back 2x150bp reads, since the max position is around 130bp or a little higher. So either the libraries were made incorrectly, or size-selection was done improperly (or skipped), or something went wrong in sequencing. Depending on your actual target insert size, and who did those steps, you may be eligible for a free replacement run, considering that you got less than half of the data you paid for. A length histogram and insert size histogram would be helpful, in fact. Using the BBMap package, and assuming you have files r1.fq and r2.fq containing your adapter-trimmed (not quality-trimmed) reads:

      readlength.sh in=r#.fq bin=1 nzo out=lengthhist.txt

      bbmerge.sh in=r#.fq ihist=inserthist.txt xloose


      Then, if you have a reference (genome or transcriptome), I suggest you map to it to determine your actual read error rates. You can do so like this:

      bbmap.sh in=r#.fq ref=reference.fa mhist=mhist.txt ihist=ihist_mapping.txt qhist=qhist.txt qahist=qahist.txt bhist=bhist.txt slow minid=0.2


      If you don't have a reference you can make a quick assembly like this:

      tadpole.sh in=r#.fq out=contigs.fa


      ...which will not be ideal, but adequate for measuring quality metrics. Once you have those metrics it will be more clear how to proceed.

      P.S. I assumed you were trying to assemble a previously unassembled transcriptome, but I guess I actually don't know what you are trying to do. What is the goal of your experiment?
      Last edited by Brian Bushnell; 10-27-2015, 09:30 AM.

      Comment

      • BastianOldenkott
        Junior Member
        • Oct 2015
        • 4

        #4
        Reply

        Hey Bukowski and Brian ,

        thank you for your quick replies. I guess your opinions are quite contrary (if I interpret Bukowski right).

        Both: I analyzed the untrimmed data again using PRINSEQ:


        Bukowski: Do you think the data can be assembled as it is? Do you see any problems in the 130 bp kmer peak?
        I want to use Trinity for assembly. Can you recommend any settings or extensions, important for evaluation of this particular data?

        Brian: The data I achieved from the company had read lengthes of 150bp, but I trimmed them already with Trimmomatic-0.33 (Headcrop 14--> 136 bp). The 'raw' (adapter trimmed) files have been checked with PRINSEQ again (see above). Based on my limited knowledge of NextGen sequencing, I cannot really see that the results are too bad (Except for the quality drop in the reverse sequences). Can you explain a little further, please?
        I will also follow your suggested pipeline and will give you the results asap, thank you very much for the input. My experiment aims mostly for analysis of organellar transcripts and a certain gene family, named 'PPR-DYW'. So far, the transcriptomes of two sister taxa from the same genus are available, but we expect highly divergent sequences in the mitochondrion.


        Best regards,

        Bastian

        Comment

        • GenoMax
          Senior Member
          • Feb 2008
          • 7142

          #5
          @Bastian: Please don't trim data by brute force. You are likely throwing away good data for no reason. As @Bukowski indicated the "bias" seen in the first few cycles is characteristic of RNAseq and is "normal". Instead what you should do is pass your sequences through a trimming program (if the reads have been "cleaned" already every one should come through) and then go ahead and try Trinity out (and Brian's suggestions too).

          Comment

          • Brian Bushnell
            Super Moderator
            • Jan 2014
            • 2709

            #6
            The untrimmed data looks fine, but you can't get much useful info from those charts, anyway. The question is what it will look like after proper adapter trimming. If the reads end up 130bp, then the insert size was way too short.

            Comment

            • BastianOldenkott
              Junior Member
              • Oct 2015
              • 4

              #7
              @GenoMax: Thank you for your suggestions. Could you recommend a trimming program besides trimmomatic? Or would you just change the parameters? When I trimmed the sequences I used the following: ILLUMINACLIP:TruSeq3-PE-2.fa:2:30:10 HEADCROP:14 SLIDINGWINDOW:4:15 MINLEN:50 (Although, removing the adapter was unnecessary, since the data we got from the company was already cleaned from adapter sequences.)
              Or: Since trimmomatic is already integrated in trinity by default, should I not trim before starting the assembly and use the internal trimmomatic?

              All the best,

              Bastian

              Comment

              • GenoMax
                Senior Member
                • Feb 2008
                • 7142

                #8
                @Bastian: Using trimmomatic in trinity is one option or you can use BBDuk :-)

                If there are no adapters to begin with all reads should survive.

                Comment

                Latest Articles

                Collapse

                • kinpict.com
                  Reply to 16S/ITS Profiling vs. Shotgun Metagenomics: What Changes in Your Workflow?
                  by kinpict.com
                  The part about this topic feels surprisingly grounded, and the details on the page is the bit that made me slow down. I’d keep <a href="https://kinpict.com/">ai family photo generator</a> bookmarked for later.
                  Today, 06:37 PM
                • SEQadmin2
                  16S/ITS Profiling vs. Shotgun Metagenomics: What Changes in Your Workflow?
                  by SEQadmin2


                  NGS has revolutionized clinical microbiology by offering new ways to identify and surveil pathogens without prior knowledge of the target. One popular approach is 16S rRNA and ITS amplicon sequencing, which targets specific microbial markers. But studies are increasingly incorporating shotgun metagenomics, a technique that sequences all DNA from a sample without targeting specific microbial markers. This approach allows more detailed taxonomic classification,...
                  10-30-2026, 06:46 AM

                ad_right_rmr

                Collapse

                News

                Collapse

                Topics Statistics Last Post
                Started by SEQadmin2, 11-12-2026, 07:59 AM
                0 responses
                27 views
                0 reactions
                Last Post SEQadmin2  
                Started by SEQadmin2, 11-05-2026, 09:25 AM
                0 responses
                35 views
                0 reactions
                Last Post SEQadmin2  
                Started by SEQadmin2, 11-03-2026, 11:54 AM
                2 responses
                56 views
                0 reactions
                Last Post kinpict.com  
                Started by SEQadmin2, 10-28-2026, 09:57 AM
                0 responses
                175 views
                0 reactions
                Last Post SEQadmin2  
                Working...