Unconfigured Ad

Collapse
X
 
  • Time
  • Show
Clear All
new posts
  • dnusol
    Senior Member
    • Jul 2009
    • 136

    #1

    cufflinks detecting single-end when paired-end used

    Dear users,

    I am running the same commands for a set of four paired-end lanes in tophat and cufflinks. But when running cufflinks on the tophat .bam output, some of the lanes are detected as single-end while others are correctly detected as paired-end. How could this be? I show you the commands for the first lane which is wrongly detected with cufflinks stdout

    $ tophat -r 200 -p 8 --mate-std-dev 40 --solexa1.3-quals --library-type fr-unstranded -o ./tophat_s1 -g 1 a_thaliana /Data/s_1_1_QC_sequence.fq /Data/s_1_2_QC_sequence.fq

    $ cufflinks -o ./tophat_s1/cufflinks -p 8 -N --library-type fr-unstranded ./tophat_s1/accepted_hits.bam
    [12:02:53] Inspecting reads and determining fragment length distribution.
    > Processed 35625 loci. [*************************] 100%
    > Map Properties:
    > Upper Quartile Mass: 444119.98
    > Read Type: 105bp single-end
    > Fragment Length Distribution: Gaussian (default)
    > Estimated Mean: 217.34
    > Estimated Std Dev: 65.65
    [12:03:32] Assembling transcripts and estimating abundances.
    > Processed 35657 loci. [*************************] 100%

    Your comments are greatly appreciated.
    Thanks

    D.
    Edit: my program versions:
    TopHat (v1.1.4)
    Bowtie version: 0.12.7.0
    Samtools version: 0.1.11.0
    Cufflinks version: 0.9.2
    Last edited by dnusol; 01-31-2011, 04:21 AM. Reason: include version info
  • adarob
    Member
    • Jul 2010
    • 71

    #2
    Are you sure that all of your paired fastq files have the same name for both reads?

    Comment

    • Jon_Keats
      Senior Member
      • Mar 2010
      • 279

      #3
      From manual
      When running TopHat with paired ends, it is critical that the *_1 files an the *_2 files appear in separate comma separated lists, and that the order of the files in the two lists is the same.
      Thus your file names must end with myfile_1.fq and myfile_2.fq

      Comment

      • dnusol
        Senior Member
        • Jul 2009
        • 136

        #4
        Thanks adarob and John for your answers but that does not solve the error I am finding. I have renamed the files so that they are called s_1_1.fq and s_1_2.fq and I still get that cufflinks reports the reads as single-end. Furthermore this issue does not happen all the time because for other lanes with the same naming convention, i.e. s_N_1_QC_sequence.fq and s_N_"_QC_sequence.fq, cufflinks reports them as paired-end

        So this is a new try modifying the name to follow "convention":
        $ tophat -r 200 -p 8 --mate-std-dev 40 --solexa1.3-quals --library-type fr-unstranded -o ./tophat_s1 -g 1 a_thaliana /Data/s_1_1.fq /Data/s_1_2.fq

        $ cufflinks -o ./tophat_s1/cufflinks -p 8 -N --library-type fr-unstranded ./tophat_s1/accepted_hits.bam
        [11:57:53] Inspecting reads and determining fragment length distribution.
        > Processed 35812 loci. [*************************] 100%
        > Map Properties:
        > Upper Quartile Mass: 445776.00
        > Read Type: 105bp single-end
        > Fragment Length Distribution: Gaussian (default)
        > Estimated Mean: 217.34
        > Estimated Std Dev: 65.65
        [11:58:32] Assembling transcripts and estimating abundances.
        > Processed 35845 loci.

        And this is an old try with other lane that gives good results

        $ tophat -r 200 -p 8 --mate-std-dev 40 --solexa1.3-quals --library-type fr-unstranded -o ./tophat_s3 -g 1 a_thaliana /Data/s_3_1_QC_sequence.fq /Data/s_3_2_QC_sequence.fq

        $cufflinks-0.9.2/cufflinks -o ./tophat_s3/cufflinks -I 11000 -p 8 -N --library-type fr-unstranded ./tophat_s3/accepted_hits.bam
        [12:05:41] Inspecting reads and determining fragment length distribution.
        > Processed 34538 loci. [*************************] 100%
        > Map Properties:
        > Upper Quartile Mass: 498434.94
        > Read Type: 105bp paired-end
        > Fragment Length Distribution: Gaussian (default)
        > Estimated Mean: 217.34
        > Estimated Std Dev: 65.65
        [12:06:24] Assembling transcripts and estimating abundances.
        > Processed 34563 loci. [*************************] 100%


        Can you suggest anything else I can try?

        D.

        Comment

        • Jon_Keats
          Senior Member
          • Mar 2010
          • 279

          #5
          The only suggestions I'd have left are:

          1) update to the most recent versions of tophat, cufflinks, bowtie
          2) double check the integrity of the input files that are failing.
          - Are they the same size in bytes?
          - Are they in the same order, run head and tail on both files and compare
          - Does your core generate MD5 sums on the original .fq if so run a checksum
          3) though things are not working I also be worried that the mean and STD for both runs are identical, that seems hard to believe.

          Comment

          • adarob
            Member
            • Jul 2010
            • 71

            #6
            Can you paste the first few reads from both ends of the fastq files that are giving you problems?

            Comment

            • dnusol
              Senior Member
              • Jul 2009
              • 136

              #7
              Thanks for your suggestions. I think I see where you are aming at. So the problem could be that after doing QC and removing reads with low quality values on each file separately, the two files from a lane ended up with different number of reads and this is not correct . So initially both s_1_1_sequence.fq and s_1_2_sequence.fq had 32193587 reads and after QC, the numbers are as follow:
              s_1_1_sequence.fq -- 15590194 reads
              s_1_2_sequence.fq -- 16385365 reads

              So I guess the read-pairing is lost for some reads. And these are the first and last few reads for both files

              $ head s_1_1_QC_sequence.fq
              @ILLUMINA-GA_191110:1:1:4938:1104#0/1
              CGACAATCCTGTAGGTAAGGGCATGATTACCATATTTGATGAGATTTTCCTTATCAATAAGGAAATCATGGTCGCCATCGAGTTCCCAAAATCTGCAGTATATCA
              +ILLUMINA-GA_191110:1:1:4938:1104#0/1
              hhhhhhhhhhgehhhWeeedffgchghhhchggfhhhhhehhgghhhhaghh_hhhhhhfhcghhcehbgdaceahdaedac__acfcdceaaecaac\aac_aa
              @ILLUMINA-GA_191110:1:1:5113:1105#0/1
              TTCACTTTTCTTTGATTCCCTTCTAGACTGTTGTCAATAATGACTCTGATGAATAAATCTTCGTCTAGCTCTGATCCTATGGATTGCCATCTATGAACAAGCTTG
              +ILLUMINA-GA_191110:1:1:5113:1105#0/1
              hhhhhhhghghehhhgghehhgddhhfhghhfcfhghfhfggdhghdh]ghghhfhh`ehhhgfgfWghdgfeWfeg_daadRbdabdd_[dadaaba[b]_BBB
              @ILLUMINA-GA_191110:1:1:5938:1104#0/1
              GGAGAACTATGTGAATAGCCGTTCCTTGAAGCATGCTCGTGACATATATAGGCAAATTCGTGAACATGTTGAACAGATAGGCTTTAATGTGTCTTCATGCGGAAA

              $ head s_1_2_QC_sequence.fq
              @ILLUMINA-GA_191110:1:1:5233:1161#0/2
              ATGCTAATGAGGTCATTGCTAATAGAGCAGCTGAGANTCTTGGTCGCAAACGTGGTGAGAAATGTGTGCACCCAAATGACCATGTGAACAGATCACAATCTTCTA
              +ILLUMINA-GA_191110:1:1:5233:1161#0/2
              fhhhhhchhahdehhhhhhhhhhhehdfcgddfaf_F^a_\^]Z]X[YXYZ[YZ\\daaa``_`[daebade_edaa_a]W^]_Sa_a_ad``Z__b___aaaa]
              @ILLUMINA-GA_191110:1:1:6770:1157#0/2
              TGACGTCTGGTGAAGCTGTCAAGTACAAGAGTTCTTNGGACGCCTTCAAGCAGATCCTCANCCTTCAAGAGCTCCCTCTGGTGCCTGGATCTCAACCATGTAANC
              +ILLUMINA-GA_191110:1:1:6770:1157#0/2
              ggaggggggeggagggggeg_dfdaff[facafcfdEdd^bbbdbgg]Rcebe_W]^\^WGYa^^_[^^Zc[]dbc_aaabMdba_aa\Yaaca]baabd]X]G^
              @ILLUMINA-GA_191110:1:1:8784:1163#0/2
              GCTTGTTCTTGCGTAGCCACATTAATGAACCTAGTGNAGCTAGAGATATCGTGAACACCAGATTTGCATTGGCTTCAAGCCCTTGCAAAACATAATCCCAAGTGA


              $ tail s_1_1_QC_sequence.fq
              +ILLUMINA-GA_191110:1:100:18210:21435#0/1
              hghhhhhchheghhhhghhhhhhhffhhfhhhgfhchhhhhhhhhhfghghhhhhhhfgehaghhghggghhgdgeghgdhgcgdfgfggeggghfffgcffggg
              @ILLUMINA-GA_191110:1:100:18834:21433#0/1
              AGAGGATTATTGCTGAGAGGTTTGGGAAGAAGAAAGGTGGGAGTAGTGTTAAGAAGACGAGTTCGGTTAGGAAGAAGAAGAAGCGTGTTTCTGATGAGTCTGATT
              +ILLUMINA-GA_191110:1:100:18834:21433#0/1
              hcfhhhhhghhhhfhchhgghhhhhgfffahg]hgfdVff_\e^dfbfdfhhghg]cffcf_cfchcdhecehgfd]hhedceffTb^bbaaaR[a_aZabbabd
              @ILLUMINA-GA_191110:1:100:19124:21432#0/1
              GTAAATGATAAGGAAATCATTCATTTTTGTCATGAAGAACATAATCTAAGACTTGGTGGTGATGATGATGTTACCCGTTATGAAAAGATGCTGTGCGACGCTTGC
              +ILLUMINA-GA_191110:1:100:19124:21432#0/1
              f`fdfdff[f^faffdffcffffcff^ffVfffdffafffaafffgfgfggggg_f_faJa_W_[K^^Z\YU\aVQKWUUW^Z^^[^WI^YYWU\decebeabac

              $ tail s_1_2_QC_sequence.fq
              +ILLUMINA-GA_191110:1:100:18069:21438#0/2
              hhhhhhhhhghhhghhghhhhhfhghhghhhfhhhhhghhhghhhhhhhhfehghehhghhhhhggfhfhfgghghhhhhgehhhggghghggehgggfhhggga
              @ILLUMINA-GA_191110:1:100:18210:21435#0/2
              TGCCAGTCTTAGCTTGCATAGATTTGATTGTTTCACCTCCTTTACCAATTATCAAACCAACCTTGTTATTCGGAATTTTCATAACAAATTGATCAGCCCCTGCTT
              +ILLUMINA-GA_191110:1:100:18210:21435#0/2
              hghhhhhhhhaffffhhhhggehhhhdhghhhghhhhhhhhhghhfhhhhhhhhhghhhhhhhhhhhhhhdhahghhfhhhhcggghhhhfhhggghhchgghh]
              @ILLUMINA-GA_191110:1:100:18834:21433#0/2
              CAGACTCATCAGAATCATCTTCATCTCTCTTTCTTCCTCTCCTCTCCTTTCTTCTCTTACTCCTTCCCTCTTCCTCATCCTCAGACTCACTCAAACTCCTTCTCT
              +ILLUMINA-GA_191110:1:100:18834:21433#0/2
              hhchhahhghhhghhhgghghhgdhhggfhgfgeggegcddfd_aedcdde_ebdggdbddffbdcdgddcfffcda]_d[^ZXYa\^Z_ad_^bc\_`VZ^^^^

              I understand that having different reads may affect the analysis but remember that my analysis pipeline is the same for other lanes and other lanes are detected as paired-ends!
              For s_3_1_sequence.fq and s_3_2_sequence.fq had 36272340 reads and after QC, the numbers are as follow:
              s_3_1_sequence.fq -- 15265617 reads
              s_3_2_sequence.fq -- 19079615 reads

              and this time they are detected as paired-end reads by cufflinks.

              As an aside, coming from this discussion, do you know of any piece of software that may do QC filtering on paired-end files maintaining the read-pairing?

              Comment

              • Jon_Keats
                Senior Member
                • Mar 2010
                • 279

                #8
                I'm guessing you found the problem. I'm not sure how much more help I can be as I just use the fastq files from our core were each file is identical. How are you generating these files? I'm a bit ignorant of the on machine steps, but my understanding was that the illumina qseq files are the unfiltered files and the "s_1_sequence.txt" files are those passing illumina filtering and the reads are paired properly. If you are filtering the "s_1_sequence.txt" files this may not be necessary and I doubt it is a common step (not that it would be incorrect to do so).

                In regards to the one that is working, I still don't have a good answer but perhaps it keeps the correct order for a part of the file?

                I'd suggest getting the input files to be the same number of reads with matching read IDs (ie. the s_1_sequence.txt files) renaming to the expected tophat convention (s_1_sequence_1.fq and s_1_sequence_2.fq) and that should work as expected.

                Comment

                • dnusol
                  Senior Member
                  • Jul 2009
                  • 136

                  #9
                  Hi Jon, thanks for your input.
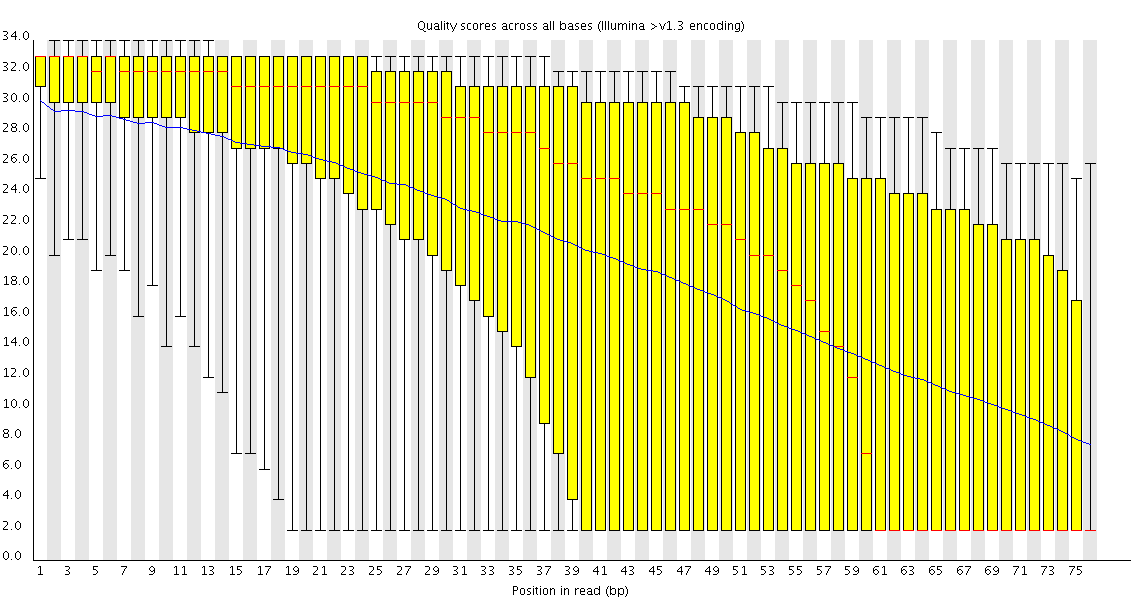
                  If I am not wrong, illumina filtering step is different from fastx QC filtering. Actually, if you have a look at the Phred scores for the raw _sequence.txt files in my experiment, supposing they are already quality filtered by Illumina, I shouldn't see the gradual drop in QC values down to below Q20 that I am actually seeing. This is why I filtered out some reads.

                  In this link


                  you could see in the first image an example of the kind of graph I am getting. They suggest trimming but I rather filter complete reads below a threshold this time.

                  I am now trying with the complete raw _sequence.txt file from illumina without filtering to see if the error comes up again.

                  Thanks

                  Dave

                  Comment

                  Latest Articles

                  Collapse

                  • SEQadmin2
                    Multiomic Liquid Biopsy: What DNA/RNA Panels Reveal That DNA Alone Can’t
                    by SEQadmin2


                    Tumors contain complex mixtures of cell populations that evolve in response to treatment and host-specific factors. Tissue biopsies provide only static snapshots of a tumor’s state. But what if we could follow that evolution over time using a minimally invasive technique?

                    Liquid biopsies can detect tumor-derived material circulating in the bloodstream, providing a way to study treatment response, detect emerging resistance, and discover new biomarkers. Circulating
                    ...
                    10-14-2026, 09:55 AM
                  • SEQadmin2
                    New Genomics Technologies Take Aim at Long-Standing Limits
                    by SEQadmin2


                    Researchers using sequencing and genomics tools often have to make trade-offs. They can choose between speed or scale, short reads or long-range information, or targeted panels or a view of the whole transcriptome. New technologies that have been released this year are built to address those tough choices.

                    We asked six companies the same four questions to learn about their latest products. The new technologies bring a lot to the table, including rethinking sequencing
                    ...
                    09-28-2026, 10:25 AM

                  ad_right_rmr

                  Collapse

                  News

                  Collapse

                  Topics Statistics Last Post
                  Started by SEQadmin2, 10-15-2026, 10:52 AM
                  0 responses
                  26 views
                  0 reactions
                  Last Post SEQadmin2  
                  Started by SEQadmin2, 10-14-2026, 05:39 AM
                  0 responses
                  34 views
                  0 reactions
                  Last Post SEQadmin2  
                  Started by SEQadmin2, 10-13-2026, 09:56 AM
                  0 responses
                  31 views
                  0 reactions
                  Last Post SEQadmin2  
                  Started by SEQadmin2, 10-09-2026, 11:14 AM
                  0 responses
                  28 views
                  0 reactions
                  Last Post SEQadmin2  
                  Working...