
I wondering if there is any formula to estimate number of unique reads from FastQC Sequence Duplication Level output. For instance, in a set of 1M reads with 80% sequence duplication level what would be the estimated minimum and maximum of unique reads?
-
-
It would seem that the answer is 200,000 unique reads, but I don't know for sure.
You could download BBTools and run "dedupe.sh" on the dataset to get an exact number:
dedupe.sh in=reads.fq out=clean.fq
It works on single-ended or paired reads; for paired it only declares them duplicates if both reads match. Also, it supports variable #edits or substitutions, if you want, though by default it just looks for exact matches. -
Interpreting the FastQC duplication level plots is actually quite complicated.
See Simon Andrews' blog posts about this:
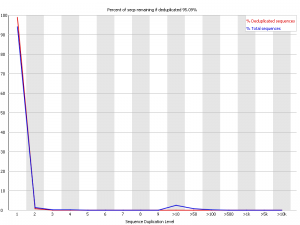
Comment
-
Thanks Brian and mastal for your comments and suggestions. I am only interested to know the number of unique reads from sequencing my libraries and I am reluctant to use any other tool since I get FastQC with other useful information. I wonder if someone could comment if a formula like this one: "(1-Sequence Duplication level%) x total number of reads= # of unique reads" will give correct answer or should some coefficients be factored in the formula.Comment
-
What I meant was, you can just run dedupe once on one dataset to confirm that the formula "(1-Sequence Duplication level%) x total number of reads= # of unique reads" is correct, or possibly derive a different formula, then go back to using FastQC. Dedupe prints the exact number (and percent) of duplicates.Comment


-
Tumors contain complex mixtures of cell populations that evolve in response to treatment and host-specific factors. Tissue biopsies provide only static snapshots of a tumor’s state. But what if we could follow that evolution over time using a minimally invasive technique?
Liquid biopsies can detect tumor-derived material circulating in the bloodstream, providing a way to study treatment response, detect emerging resistance, and discover new biomarkers. Circulating...10-14-2026, 09:55 AM
Comment